Quaerit is an online archive of academic metadata — journals, articles, researchers, topics — queryable through a user-friendly interface. For now, it contains data on a specific academic field: philosophy.
The corpus in numbers
The article records of our corpus come from open access sources only. So far, we have used OpenAlex and Crossref. Citations and references are matched through each article's DOI.
Records go through a cleaning pipeline that involves both manual and automated checks. However, not all the records have been checked yet. When a record has not been checked, this is explicitly indicated.
Our data is currently partially raw: an author may have more than one identifier, titles might be misspelled, numbers could be wrong, data may be corrupted. Cleaning the data is an ongoing task — we'll refine it by applying our cleaning pipeline, which will itself be improved.
More journals, and better coverage of the ones already in. We will add books and chapters of edited volumes, too. We will also add essential biographical information to each author's page, if available.
We will add a section dedicated to the authors' affiliations, and map the influence of academic institutions through time.
We're philosophy researchers with an interest for digital humanities, and software engineers interested in data management and analysis.
Swipe to browse
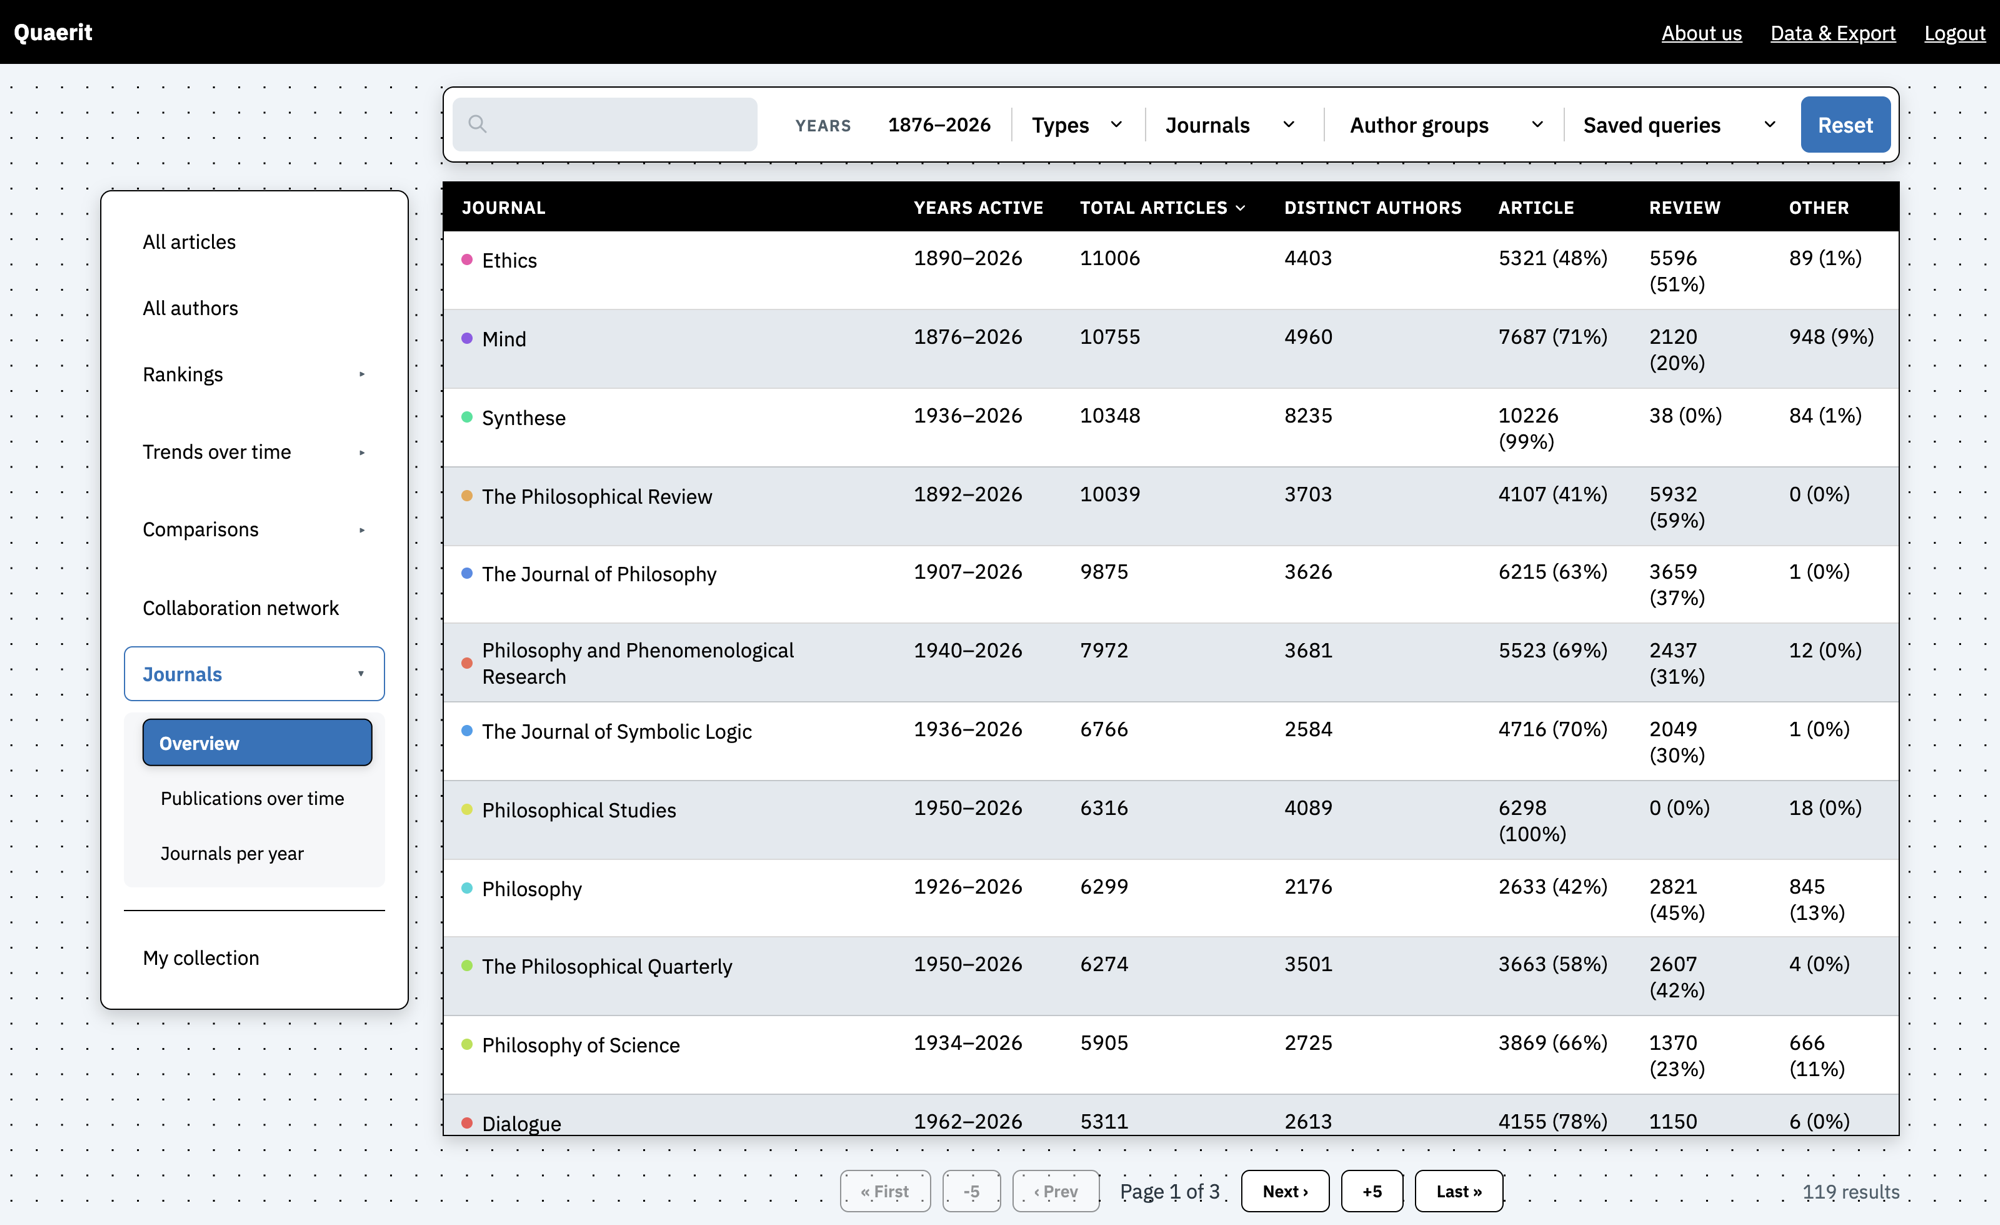
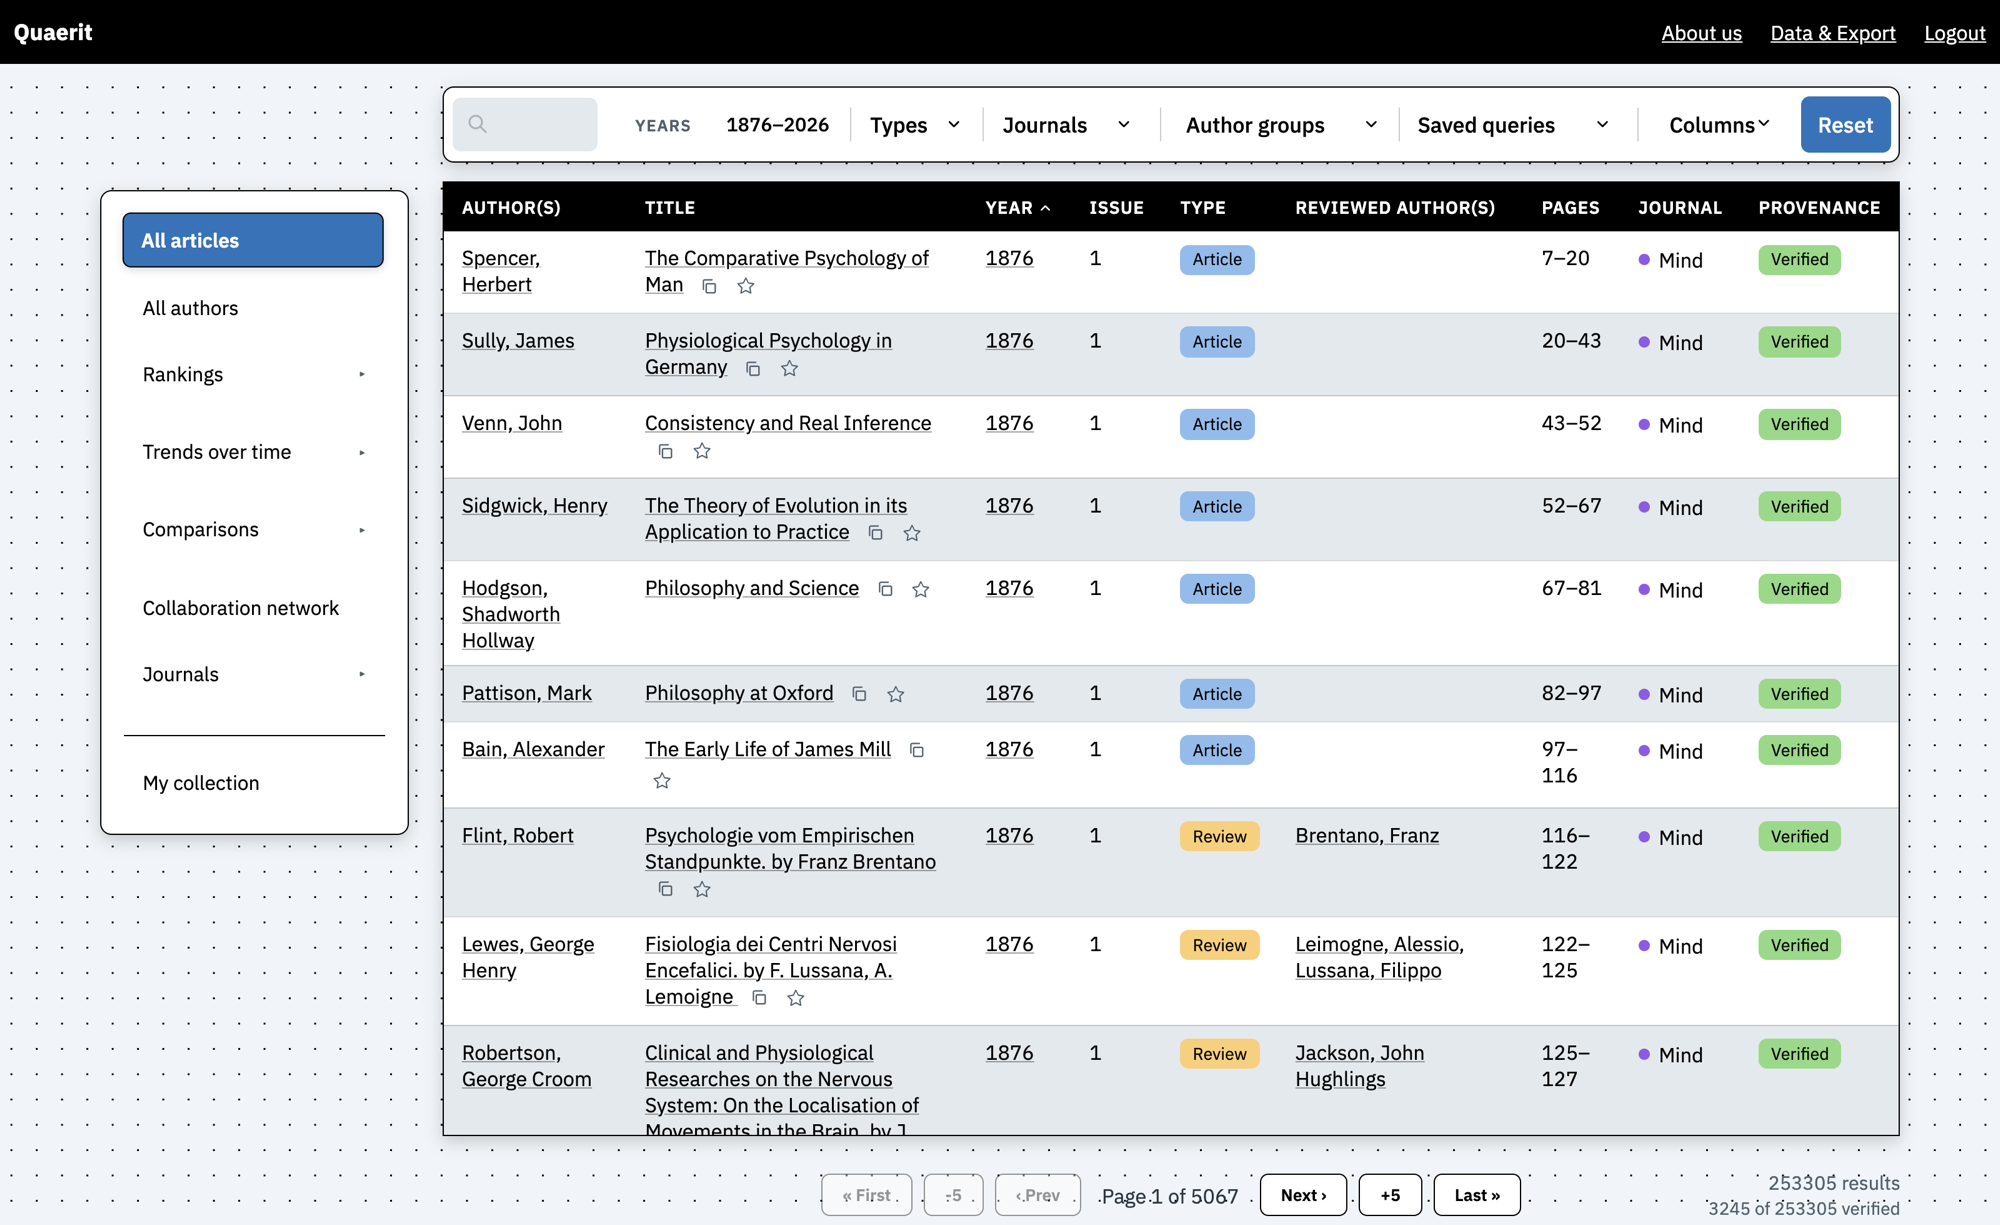
The whole corpus in one table, 253,305 rows deep, with every filter stacking on top of the last
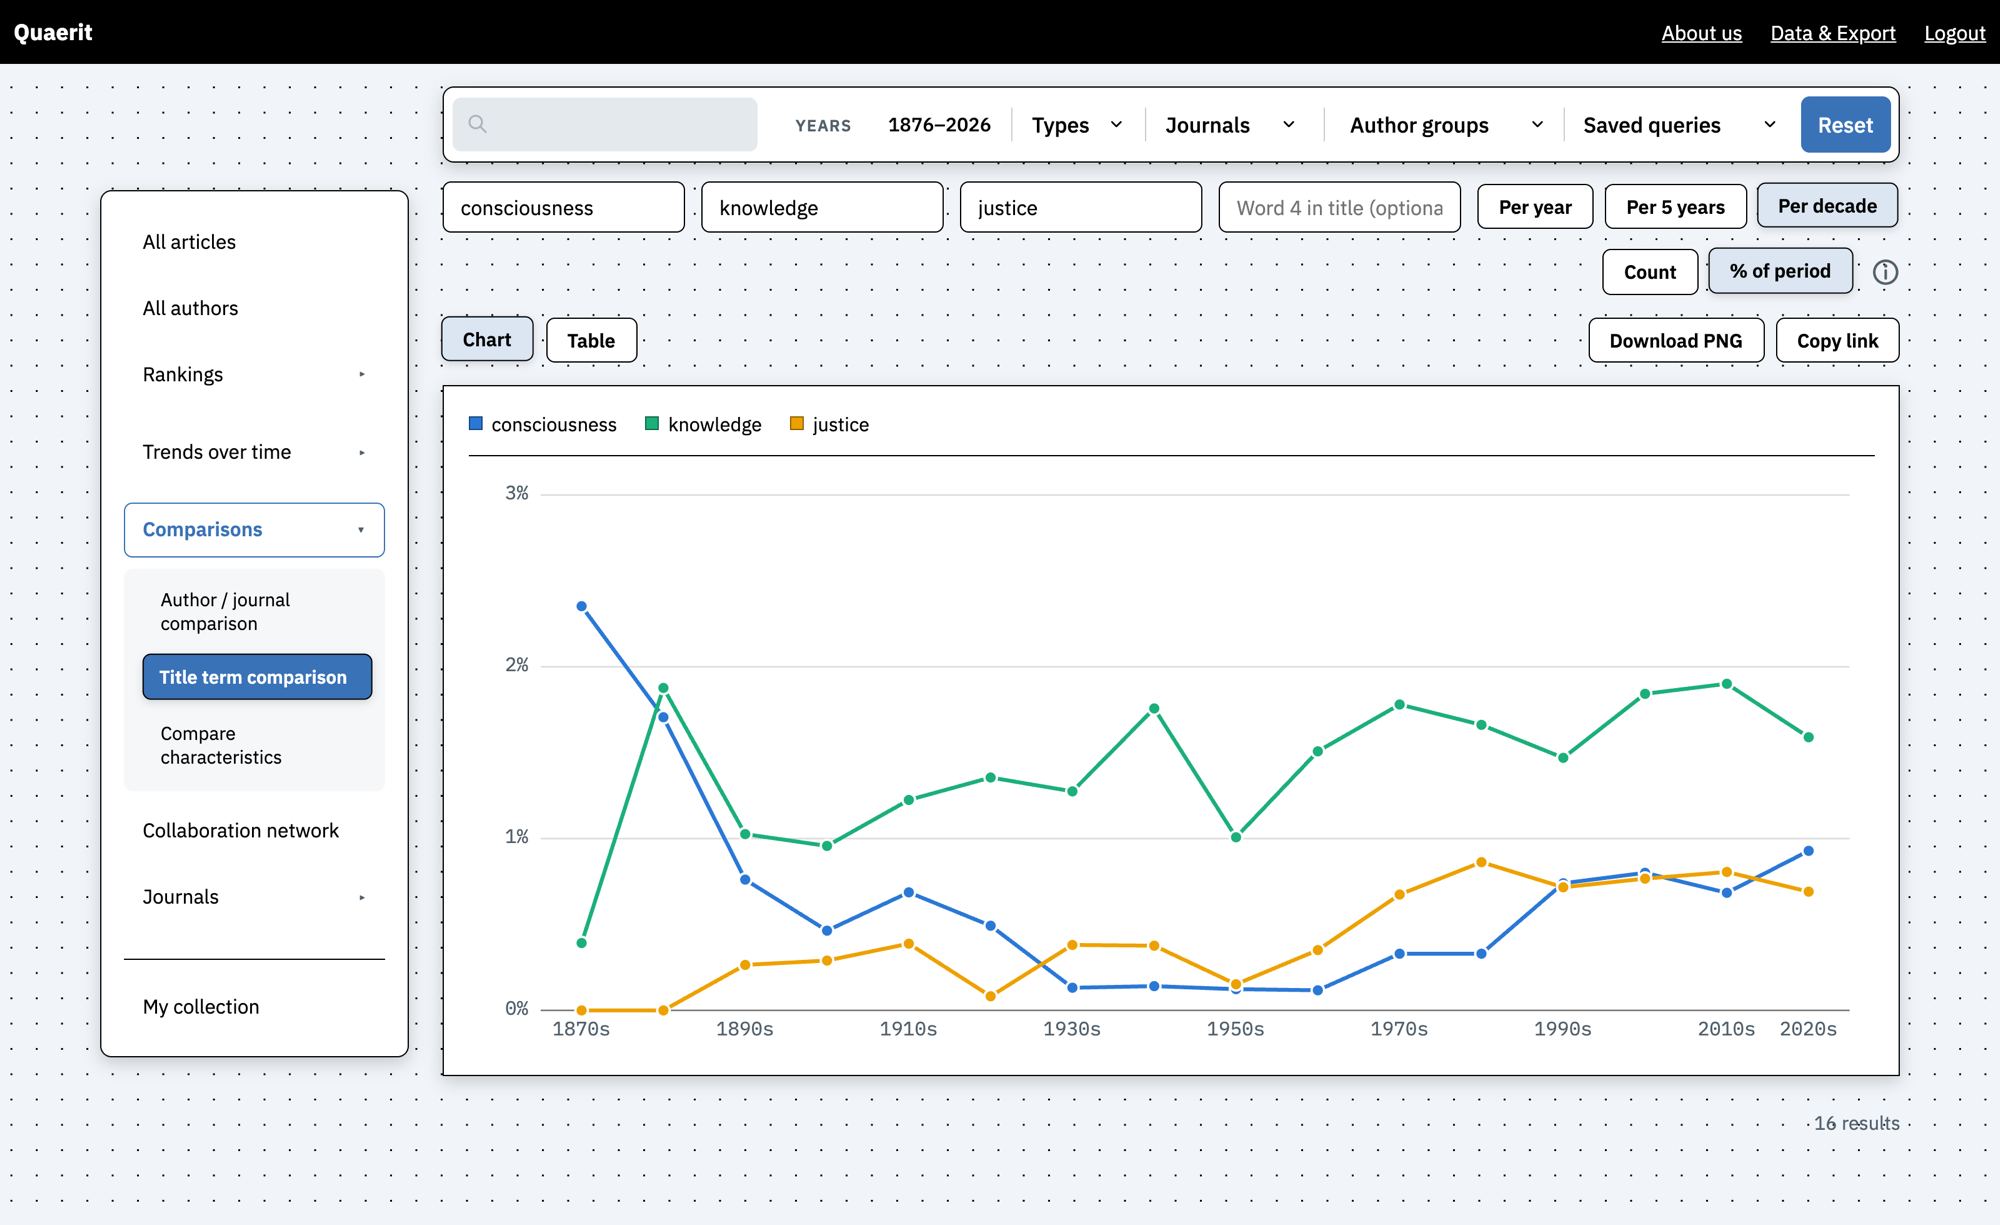
Up to four words compared across article titles over time — per year, per five years or per decade, as raw counts or as a share of each period. Every chart downloads as a PNG, and every view has a permalink that restores it exactly.
Swipe to browse